Want help applying this guide?Ask the DripTell team
A bicycle shop tests a customer call about an electric bike. The request should reach the electrical specialist. Instead, it lands with the general repair queue because an old rule still checks the product type before the fault type. Nobody notices until the customer has waited and repeated the problem.
Audit customer support routing rules by freezing a small set of representative cases, writing the expected destination and fallback for each one, and then running those exact cases through the live path. Check what happened at intake, classification, queue selection, assignment, acceptance and fallback. Change one rule at a time and rerun the same set. That is more reliable than reading a configuration screen and assuming the logic still works.
Start With the Customer Outcome
Routing is not successful merely because a case received an owner. The useful question is whether the request reached someone who could act, with the right context, within the promised time. A billing case sent quickly to a product specialist is still misrouted. A complex case sent to the right specialist with no backup is fragile rather than complete.
Write one expected outcome for every test case before opening the rule builder. Include the destination queue, eligible role, priority, context that must travel, and what should happen when nobody is available. This keeps the audit connected to the customer rather than the elegance of the rule. It also makes it easier to review the operating model behind your support workflow, not just the automation.
Microsoft describes unified routing as separate workstreams, queues, routing rules and assignment rules, with diagnostics and configuration audit logs as supporting controls in its routing setup guidance. The exact names vary by platform, but the separation is useful. A case can enter the right workstream and still fail later.
Freeze Cases Before You Touch the Rules
Choose a small set of cases that represent real decisions. A useful starter set includes a routine request, a specialist request, a high impact request, an incomplete request, a known customer with an existing owner, and a case that arrives when the preferred team is unavailable. Preserve the input exactly. Do not rewrite a subject line or add a tag between runs.
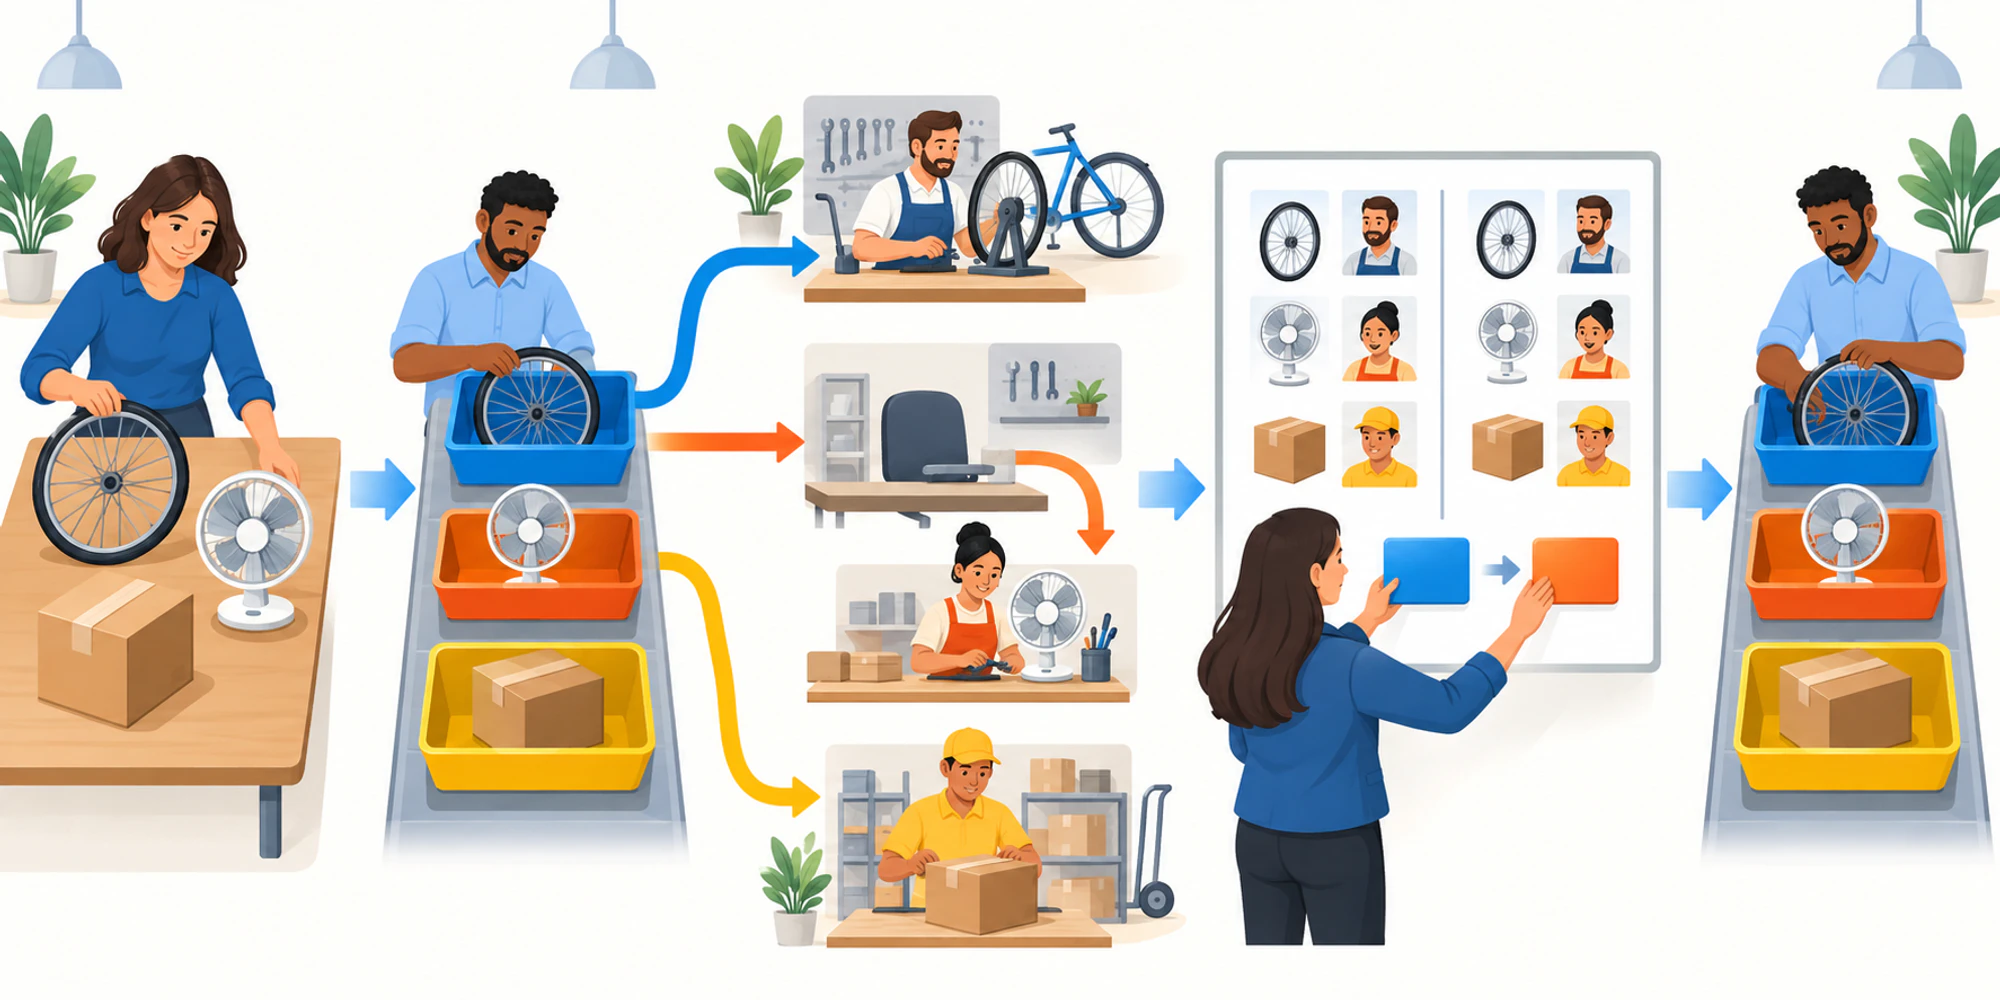
- 1Freeze the casesKeep the customer input, expected destination and reason unchanged.
- 2Use the real intakeSubmit each case through the same channel and entry path as a customer.
- 3Observe every stageCheck classification, queue, assignment, acceptance and ownership in order.
- 4Force the fallbackMake the preferred specialist unavailable and verify a safe owned alternative.
- 5Change and rerunAdjust one rule and repeat the complete frozen set, not only the failed case.
For each case, record the expected route and the reason. The reason matters. If the team cannot explain why one case outranks another, the rule may be encoding habit rather than policy. Keep the test set beside the change record in your automation workspace, so the next audit starts from the same evidence.
Run the Same Cases Through Every Branch
Use a safe test customer or controlled channel and submit each case through the same entry point a real customer uses. Do not inject it directly into the final queue. Intake, identity matching, classification and business hours can all change the route before assignment begins.
Run the happy path first, then remove one condition at a time. Mark the specialist unavailable. Fill the preferred queue to its safe capacity. Omit the category. Send the case after hours. Check whether the request waits, falls back, escalates or disappears. A fallback is not proven until the preferred path genuinely cannot accept the work.
The Microsoft routing diagnostics reference shows why the event order matters. Its evidence model follows intake, classification, route to queue and assignment, and exposes items such as the rule hit policy, queue, routed representative, capacity, presence, skills and assignment attempts. Microsoft also notes that this particular diagnostics feature is deprecated, so keep the audit method platform neutral. Use the current event trail your system supports.
Read the Route Evidence in Order
Start with the first point where expected and actual behavior diverge. A wrong queue is not an agent failure. An unaccepted offer is not necessarily a classification failure. Reading backward from the final owner encourages guesses.
| Evidence layer | What to compare | Failure it exposes | Decision owner |
|---|---|---|---|
| Intake | Channel, record type and operating window | Wrong workstream or skipped entry rule | Channel owner |
| Classification | Topic, priority, skills and customer context | Missing data or an overbroad condition | Support operations |
| Queue route | Expected queue and actual queue | Rule order, stale exception or default capture | Routing owner |
| Assignment | Eligibility, presence, capacity and attempts | Nobody qualified or capacity unavailable | Workforce lead |
| Acceptance | Offer, timeout, rejection and ownership | Notification or handoff failure | Team lead |
| Fallback | Trigger, destination and retained context | Dead end or context loss | Service owner |
Store only the evidence needed to explain the decision. Access to routing details should follow the same least privilege approach as other security controls. The audit is about system behavior, not creating a surveillance file on agents.
Change One Rule and Rerun
Make the smallest change that explains the failed case. It may be rule order, a missing default, a stale skill, an operating-hours condition or an eligibility filter. Record the old behavior, the change, the owner and the rollback point.
Then rerun the complete frozen set, not only the failed case. A good result has three parts. The corrected case reaches the intended destination. The unaffected cases behave exactly as before. The fallback still works when the preferred path is unavailable.
Do not hide manual overrides during the test. If a supervisor rescues a case, record that as an observed exception. The team inbox should make ownership visible, but visible ownership does not prove the route that created it.
What to Do When the Rule Looks Right
If the rule configuration looks correct but the outcome is wrong, inspect the data feeding it. Customer identity may not have matched. A CRM field may be empty or stale. Presence may not equal routing eligibility. Capacity may not have been released after earlier work. The audit should distinguish a good rule fed by bad state from a bad rule applied correctly.
This is where linked customer context and controlled AI assistance can help, but neither should silently rewrite the expected route. Keep a human owner for exceptions and review repeated overrides as evidence that the policy or source data needs attention.
Finish with a short route receipt for each case. Record expected destination, actual destination, first divergence, fallback result and final owner. That makes the next review faster and turns routing changes into testable operations rather than memory.
Frequently Asked Questions
How often should routing rules be audited?
Run the frozen test set after every rule, queue, skill, hours or capacity change. Also schedule a periodic review based on change frequency and risk. A stable small team may review quarterly, while a fast changing operation may need a monthly check.
What is the smallest useful routing test set?
Start with six cases covering routine work, specialist work, priority, incomplete data, existing ownership and unavailable staff. Add a permanent case whenever a real incident reveals a new branch.
Should agents be judged for misrouted cases?
Not from the final assignment alone. First verify intake, classification, queue selection, eligibility, offer delivery and fallback. Coach an agent only when the evidence shows a decision they controlled.
DripTell Editorial
Practical guidance reviewed by the DripTell product and customer workflow team.
See how DripTell checks product claims, uses primary sources and handles corrections.
Editorial and source policy