Want help applying this guide?Ask the DripTell team
At 10:15 on Monday, a delivery problem sends twice the usual number of customers into one support queue. The first instinct may be to move everyone, switch on every automation, and ask the team to work faster. That is usually how a local surge becomes a wider service problem.
The better response is calmer. Confirm that the spike is real, identify where it sits, protect the customers already waiting, and add the smallest temporary capacity move that can be reversed. Keep one person in charge of the response and define the condition that will end it.
First confirm the spike is real
One busy interval is a signal, not yet a crisis. Compare actual arrivals with the forecast for the same interval, channel, and queue. Then look at the next interval. Microsoft describes volume alerts as a comparison between actual and forecast demand over consecutive intervals, not as a reaction to one isolated number in its guidance on volume spike alerts.
Check the absolute count as well as the percentage. If the forecast was one conversation and three arrived, the increase looks enormous even though the workload may still be manageable. Also check whether the apparent surge is really longer handling time, fewer available people, a routing fault, or an old backlog becoming visible.
Assign a response owner now. That person decides when the surge is confirmed, records the start time, and prevents five supervisors from making five different changes.
Find the queue that changed
Aggregate volume can hide the useful answer. Separate the work by channel, queue, request type, and time interval. Microsoft's forecast analysis guidance keeps actual volume, forecast volume, and handle time separate and lets supervisors compare channels and queues. That distinction matters. A surge in delivery questions on WhatsApp does not justify moving people away from a stable billing queue.
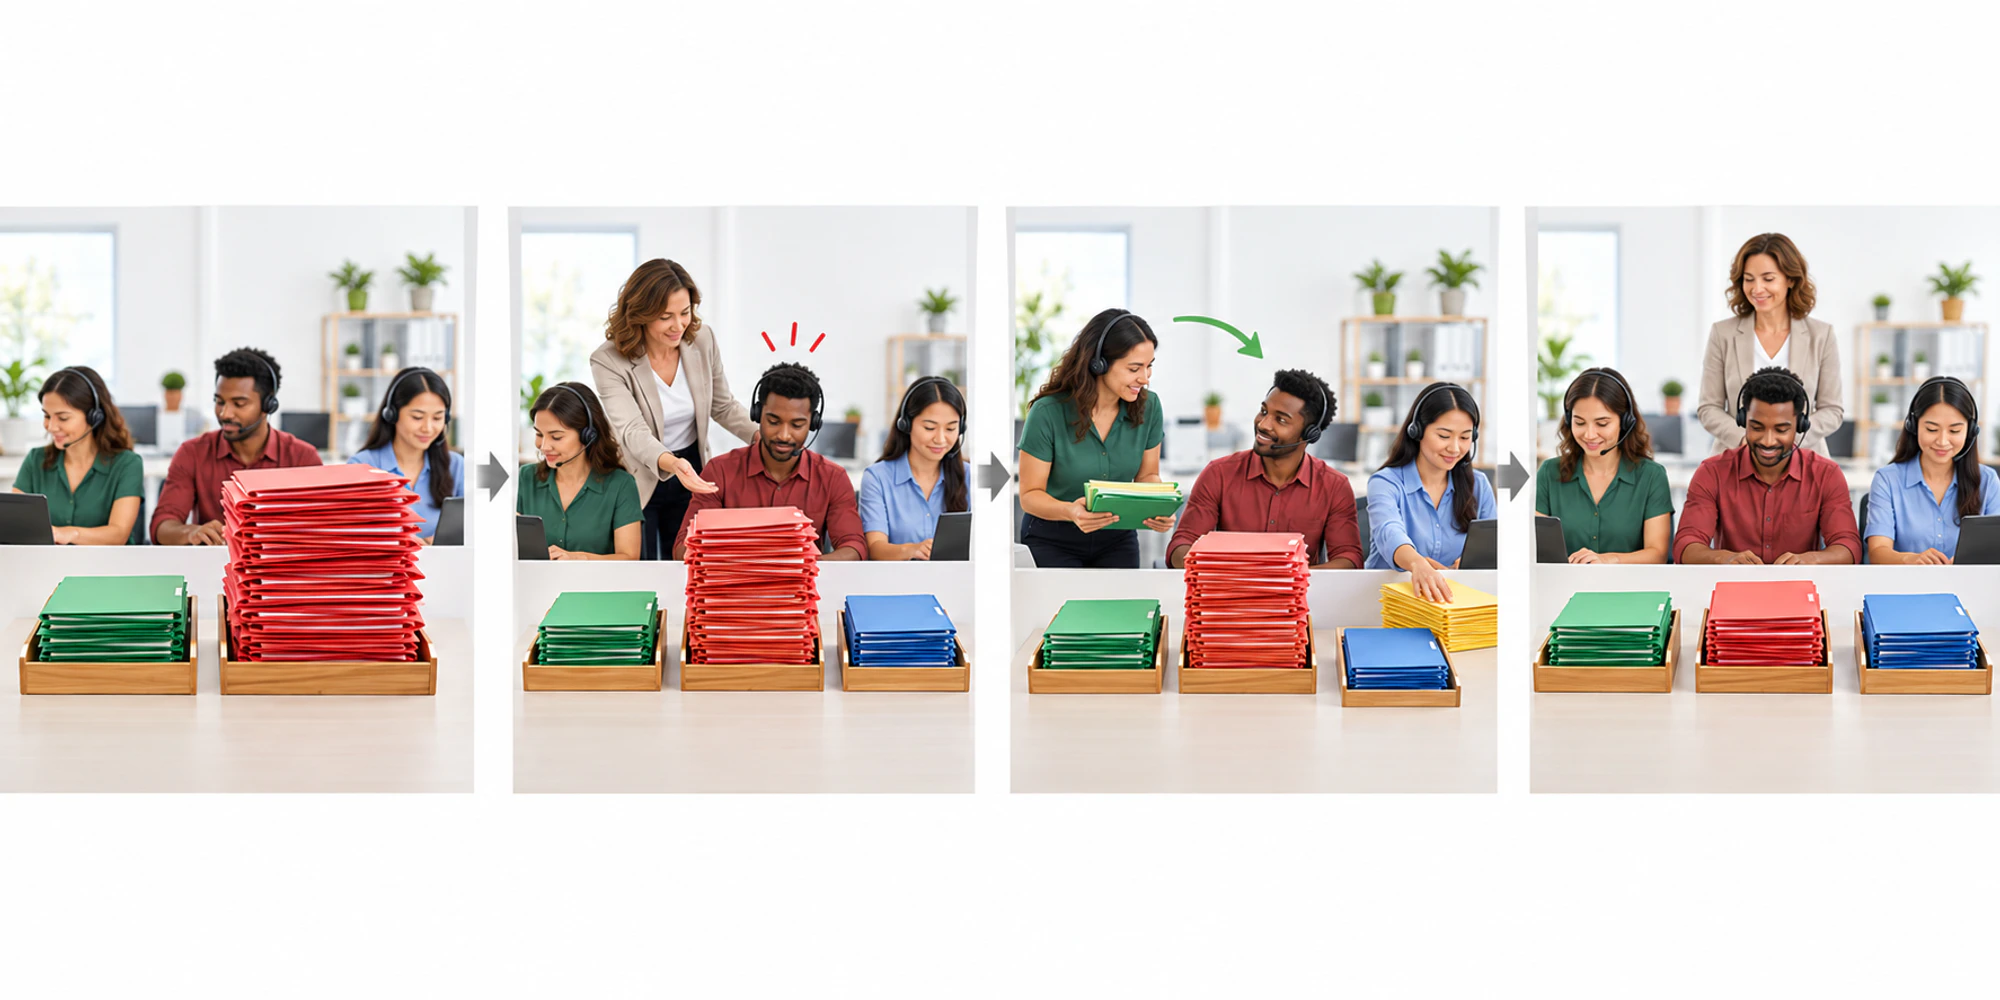
- 1ConfirmCheck that actual volume remains above the right forecast for more than one meaningful interval.
- 2LocateFind the channel, queue and request type that changed instead of alarming the whole team.
- 3ProtectKeep oldest, harmful and already owned conversations visible while the response changes.
- 4RelieveAdd one reversible capacity move and pause lower-value work before making larger changes.
- 5RecoverRemove temporary measures when the agreed signal stabilises and review what caused the miss.
Use the same view in your team inbox. Look for the queue building fastest, the oldest unassigned conversation, current availability, and whether the same issue is creating repeated contacts. Do not route more work into a lane until you know why that lane is slow.
Protect customers before moving people
A response plan should preserve ownership and age. Customers should not lose their place because the team changed routing rules. An already owned conversation should stay with its owner unless a deliberate handoff transfers the context and next action. Your automation rules can help route new arrivals, but they should not silently reshuffle active work.
Use a simple decision matrix before choosing the intervention.
| Evidence in the live queue | Immediate decision | Keep stable | Exit condition |
|---|---|---|---|
| One interval rises and the next returns to normal | Watch without moving people | Current ownership and routing | Two normal intervals |
| One queue stays above forecast while others are light | Move limited cross-trained capacity | Oldest work and specialist cases | Backlog age and arrivals stabilise |
| Volume is normal but waits rise | Investigate handle time or availability | Intake rules | Cause is found and waits recover |
| Many queues rise after one known event | Open the incident response | One response owner and customer updates | Event demand falls below the agreed threshold |
| A tiny forecast makes the percentage look extreme | Judge absolute workload first | Normal staffing | Absolute demand remains manageable |
This is also where priority discipline matters. Protect work with real harm or no workaround. Do not make every conversation urgent. A clear support operating model should keep routine work owned and visible even when it waits a little longer.
Add capacity you can remove
Start with one reversible move. Bring a cross-trained person from a genuinely quiet queue. Defer nonurgent offline work. Extend coverage for a defined period. Pause an outbound campaign that is creating avoidable replies through your campaign controls. Each move needs an owner and an end time.
Automation can absorb repetitive classification, acknowledgements, and safe self-service, but only inside a tested boundary. Use AI controls to keep uncertain or harmful cases with people. A surge is the worst time to let a new workflow make irreversible decisions.
Avoid spreading the pain blindly. Moving everyone into the busiest queue can empty other queues, create skill mismatches, and leave no capacity for the next problem. One visible temporary change is easier to measure and undo than six overlapping changes.
Tell customers what changed
If the expected response time has moved materially, say so in plain language. Give a realistic range or next update time. Do not promise that an agent will reply soon when the team cannot support that promise. Keep customer history and agreed next actions in the CRM context so a delayed reply does not force the customer to explain everything again.
The team also needs one short internal update. State the affected queue, the confirmed evidence, the temporary action, the response owner, and the next review time. That is enough. A long incident channel can become another source of work.
Close the response deliberately
Do not leave emergency routing in place because the dashboard finally looks calm. Remove temporary capacity in the reverse order it was added. Confirm that arrivals, backlog age, availability, and wait time have stabilised for the agreed period. Then check the queues that lent capacity.
The review should be small and honest. Was the forecast wrong, did one event create new demand, did handling time change, or did routing fail? Preserve the forecast snapshot and the actual interval data. Record which intervention helped and which merely moved the backlog. The aim is not to prove the forecast was good. It is to make the next response faster and less disruptive.
Frequently Asked Questions
How long should volume stay high before we act
Use more than one meaningful interval unless customer harm is immediate. The right duration depends on normal queue size and response time. Small queues usually need a longer confirmation window because a few arrivals can create a misleading percentage.
Should every support spike trigger overtime
No. First isolate the affected queue and test a smaller reversible move such as cross-trained help or deferred offline work. Overtime makes sense only when the surge is sustained and the remaining capacity gap is clear.
Can automation absorb a sudden support spike
It can handle tasks that were already tested, such as classification or safe acknowledgements. It should not be given new authority during the spike. Keep uncertain, sensitive, and high-harm decisions with people.
What should we review afterward
Compare the saved forecast with actual volume, handle time, backlog age, availability, and customer outcomes. Then decide whether to change the forecast, routing, coverage plan, or event playbook.
DripTell Editorial
Practical guidance reviewed by the DripTell product and customer workflow team.
See how DripTell checks product claims, uses primary sources and handles corrections.
Editorial and source policy