A supervisor publishes a routing playbook at 9:00. It looks clear: if a priority customer waits and the specialist team is unavailable, raise the priority and offer another path. The configuration passes validation. Ten minutes later, a real conversation takes a route nobody expected.
That is the problem to test. Dynamics 365 does not run the prose itself. When a playbook is published, a language model converts the natural-language instruction into a structured runtime format. Microsoft warns that the converted result may not fully capture the intended logic and that some deviations can appear only at runtime. A safe release therefore needs controlled conversations, changed queue conditions, observed outcomes, and a rollback decision. A successful publish is only the start.
Start with the event condition action contract
Rewrite the playbook as a small contract before opening the admin center. Name the event, every condition, the action, the queues, the channel, and the fallback. If the instruction says “when the wait becomes too long,” replace that phrase with an agreed threshold. If it says “send to an expert,” define which queue membership, presence, capacity, and skill make someone eligible.
The current Microsoft configuration guide describes conversation orchestration as a production-ready preview for voice and messaging. It requires unified routing, appropriate administrator access, configured queues and workstreams, and consumption-based billing. Playbooks are built from a trigger, conditions, and actions. Keeping the same shape in the test contract makes disagreements visible before a customer is involved.
Do not let natural wording hide ownership. An operations owner approves the intent, a queue owner confirms membership and hours, and a service lead approves the fallback experience.
Build a test pack around real routing risk
Use a training queue or another tightly controlled scope. Add only test representatives and synthetic customer records. Do not publish first to every production queue because the preview is described as production-ready. That label does not prove your wording, context variables, or dependencies are correct.
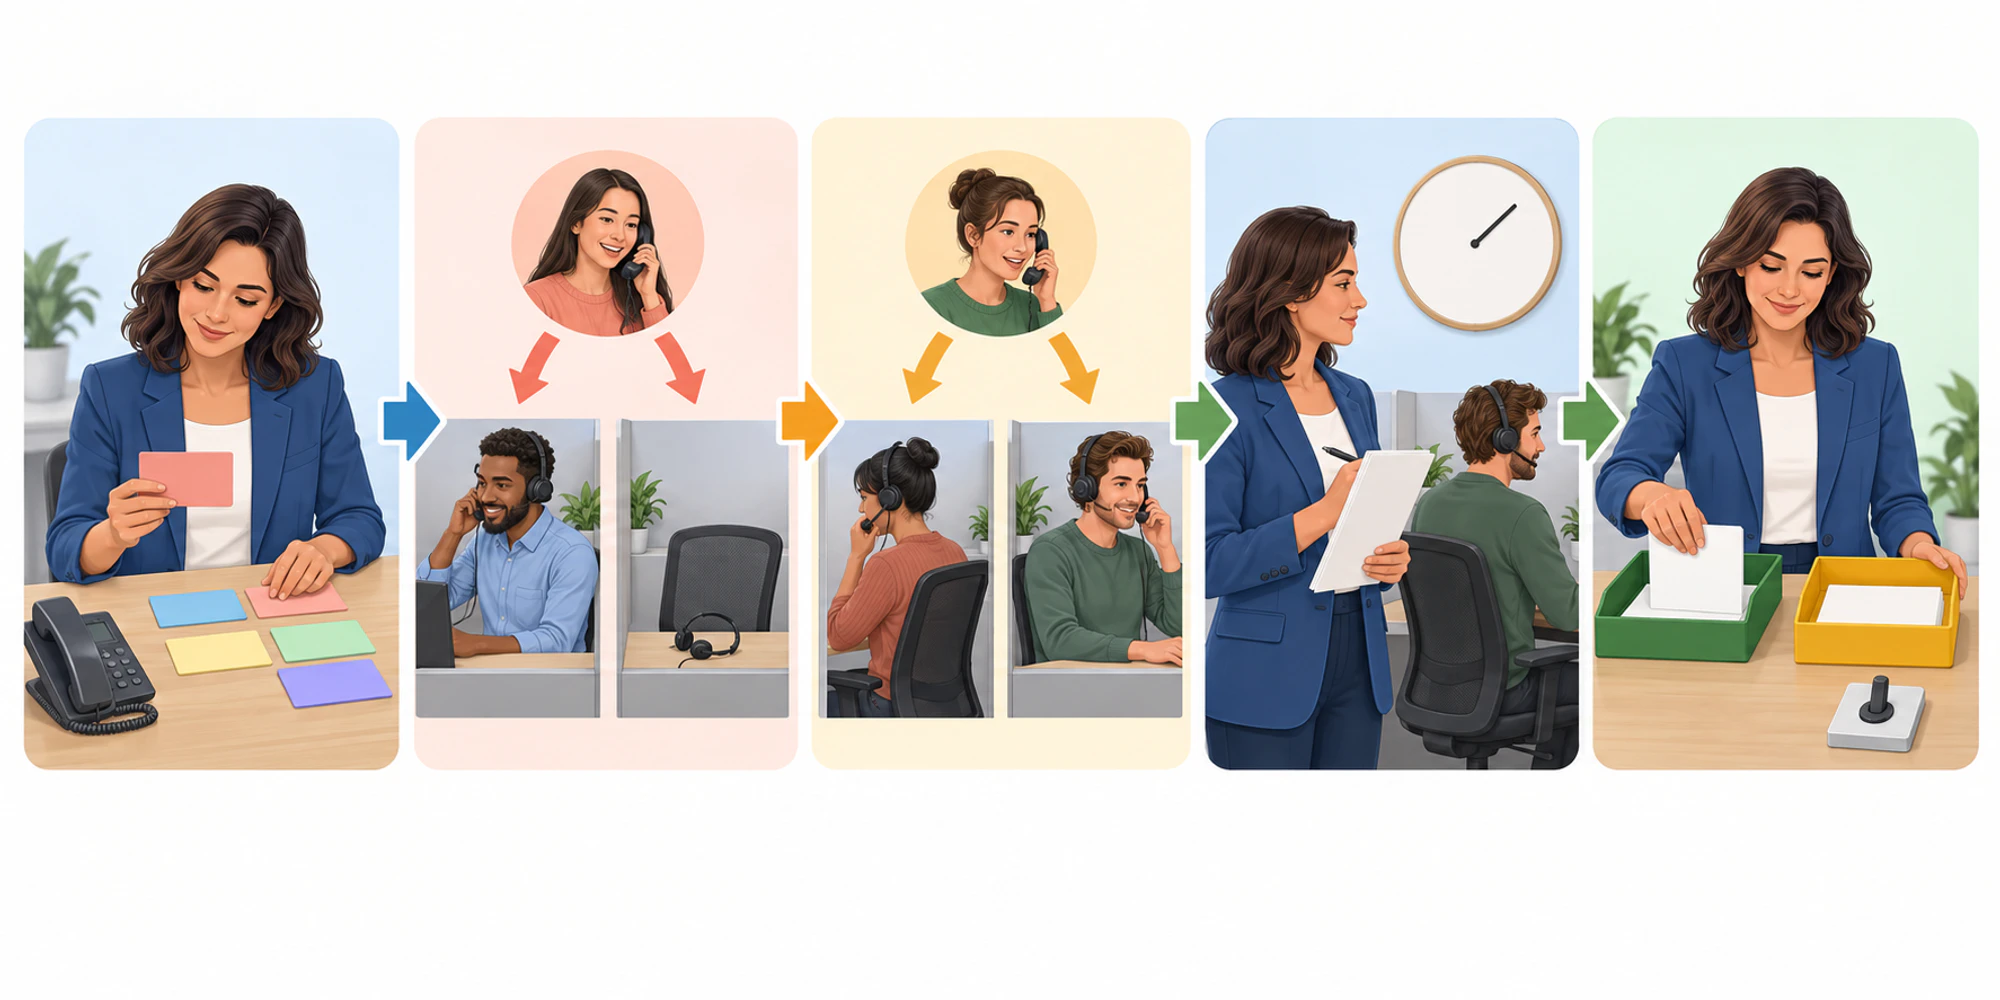
- 1Define the contractWrite the event, conditions, action, scope and fallback in exact terms.
- 2Isolate the scopeUse one training or pilot queue with synthetic records and test representatives.
- 3Test both edgesRun a clear match and a near miss before changing live conditions.
- 4Change one conditionVary presence, capacity, wait state or queue hours separately.
- 5Observe then widenCompare diagnostics with the approved route and stop on unexplained differences.
Prepare at least one conversation for each of these cases:
- a clear match that must run the action;
- a near match that must not run it;
- an eligible representative who is available and within capacity;
- the same representative unavailable, signed out, or at capacity;
- a queue that closes or becomes unstaffed while work is waiting;
- a fallback path in which the preferred destination cannot accept the conversation.
Run the cases with stable inputs first. Then change one condition at a time. That makes the cause of an unexpected route traceable. Changing the customer tier, queue state, wait threshold, and representative capacity in one run produces a result but not useful evidence.
Test what should not happen
Positive tests are easy to trust too quickly. The better test is often the near miss. A standard customer should not receive priority intended for a premium tier. A conversation one second below the agreed threshold should not escalate early. A representative outside the selected queue should not become eligible simply because they have the right skill.
Use a decision table so each expected route is agreed before execution.
| Test situation | Expected action | Evidence to retain | Release meaning |
|---|---|---|---|
| Every condition matches | Intended priority or assignment runs | Conversation identifier and diagnostics | Basic path works |
| One condition is absent | No playbook action | Unchanged route and diagnostics | Boundary is respected |
| Same queue has the same active scenario | Publication is blocked as a conflict | Validation message | Duplicate policy is prevented |
| Same queue has a different scenario | Each trigger runs only when its own event occurs | Ordered event record | Combined behavior is understood |
| Preferred representative is unavailable | Defined fallback runs | Presence, capacity, destination | No customer is stranded |
| Queue or context variable differs after migration | Test fails before broad release | Dependency check and observed route | Environment drift is caught |
Record the observed destination and time beside each row. If the team cannot explain a mismatch, stop. Do not rewrite the expected result after seeing what the system did.
Observe the runtime and not the wording
The Microsoft responsible AI FAQ says the system evaluates an event, conditions, and an action, while the language model is used during authoring to create the runtime representation. It also lists an important current limit: the feature supports English only. The same FAQ says administrators should test and monitor runtime behavior because conversion differences may be visible only when the playbook runs.
For each test conversation, capture the trigger, queue, selected context values, representative presence and capacity, action taken, final destination, and customer-facing outcome. Use conversation orchestration diagnostics rather than screenshots of the playbook sentence alone. The prose shows intent. The runtime evidence shows what actually happened.
Pay attention to ordering when more than one scenario applies. An availability-based overflow action may run immediately. A wait-time priority action can run later only if the conversation remains in the queue. Both may be valid, but the sequence must match the customer experience your team approved.
Release narrowly and keep a way back
A playbook is either a draft or active. Drafts can be changed without affecting routing. Changes to an active playbook are saved and published together, so treat that button as a production change. Microsoft also notes that deleting an active playbook stops orchestration for the corresponding queue immediately.
Start with one queue, one channel, one scenario, and a short observation window. Define the stop signal in advance: an unexplained destination, an early escalation, a stranded conversation, an unexpected customer message, or a material difference between test and production dependencies. If one appears, disable or revise the playbook, restore the previous routing behavior, and rerun the same test pack.
The discipline extends beyond this feature. Support operations need visible ownership, a shared inbox needs an assignee after automation, and a workflow builder needs stop and fallback rules. AI controls need bounded authority and security controls an audit trail. A DripTell demo can help map those handoffs without pretending one test proves the whole system.
The useful release question is not “Did the playbook publish?” It is “Did every controlled conversation take the approved path when conditions changed?”
Frequently Asked Questions
Can validation replace runtime testing
No. Validation can catch missing fields, ranges, duplicates, and some conflicts. Microsoft states that deviations in the language-model conversion may be identifiable only during runtime, so controlled conversations and diagnostics are still required.
Should the first test use a live customer queue
No. Use a narrowly scoped training or pilot queue with synthetic records and test representatives. Move to a limited real queue only after the positive, negative, capacity, overflow, and fallback cases behave as expected.
What should block publication
Block publication when the event, conditions, action, scope, dependencies, or fallback are ambiguous, or when any observed route differs from the approved result without a clear explanation. A passing configuration screen does not override unexplained runtime evidence.
Want help applying this guide?Ask the DripTell team
From reading to action
Want help applying this to your business?
Share your details. We will read the article you are on and start with a useful answer for your team.
DripTell Editorial
Practical guidance reviewed by the DripTell product and customer workflow team.
See how DripTell checks product claims, uses primary sources and handles corrections.
Editorial and source policy